Earlier this year, when software stocks were taking a beating related to the heights of AI enthusiasm, a client reached out to me for my opinion on whether AI might be used by domain experts, such as myself, to create competing products capable of supplanting established software firms like Advent and others at a fraction of the price due to a lower cost base.
At the time, I acknowledged that it was possible, but more likely to happen at smaller firms. Investment professionals are stereotypically risk-averse in their business practices and the production software they utilize to run their businesses. While the largest investment firms are better suited to tolerating risk from a resource standpoint, they are also the least likely to take on what they might consider unnecessary risk. As a result, larger firms as a whole are slower to replace mainstream products with upstart offerings that have an unproven track record.
However, a more likely possibility has emerged: firms currently running vendor software—motivated by the costs and limitations of those products—may simply create their own systems using AI to aid them in the process. I have already seen signs that some firms are doing this and feel comfortable doing so. I am not necessarily recommending it, but I understand the motivation.
If you are paying substantial fees for systems you believe you could replace, why wouldn’t you? The key here is understanding what these systems actually do. A vendor with a forty-year track record has built a product that almost certainly handles details that an AI-assisted or ‘vibe-coding’ alternative (with a relatively short window of development and testing) does not; however, that may not matter much if you are only looking for 60% to 80% of the functionality of the product you are replacing.
When I compare products in the investment space, there are clear differentiators between older-class solutions and newer-class solutions. Those differentiators once would have represented a significant hurdle for a competing product to match, but AI makes it much easier.
As an example, consider the HTML attachment below, which summarizes hypothetical investments for a fictitious company and client in a format typical of newer-class solutions. I used Claude to help me produce this last month. This is something I could have done previously if a prospective client had asked me to, but I was never tempted to do so because it would have been tedious and time-consuming to perform manually. With the assistance of frontier AI models, I was able to achieve the following result, which can easily be populated from portfolio accounting data within Axys or APX. Please note that all reporting exhibits in this blog were produced using Anthropic, OpenAI, and Perplexity models and based on fictional data; disclosures on each exhibit also restate this.
The prompt was the result of a test I performed one afternoon where I asked the best-known publicly available frontier models in the cloud, as well as the best local models I can run on my Alienware Area-51 desktop, to create what I consider to be a decent report package by today’s standards. I would love to take more credit for it, but I cannot; I simply asked Claude to do it and it was done. Perplexity also did a respectable job, though it fell slightly behind Claude’s effort, while ChatGPT’s report was clean but relatively simplistic.
The local models didn’t put up much of a fight, although I may be able to improve their performance by using frontier models to design the prompts for them. It would be nice to rerun these tests using GLM-5.3 Q4 or GLM-5.3-Flash on a Mac Studio with an M5 Ultra chip and 512GB of unified memory, but I don’t have one of those yet. Naturally, if you write better prompts than I did or possess superior hardware, your results may vary.
Claude didn’t just create a pretty mockup of data in HTML like ChatGPT and Perplexity; it created JSON blocks within the HTML that I can populate programmatically from data feeds I have already created using xPort with Axys and APX. If I wanted to build an alternative system, I would be well on my way with this type of reporting right out of the gate.
Here is what I produced with Perplexity’s assistance.
The pros and cons of building versus buying remain. AI can potentially help you maintain the code, but will your staff truly understand everything they are using? Probably not. And what will it cost to maintain that code in the future? If the system is predominantly AI-coded and not fully understood by those at your firm, that cost will be determined by the “AI gods” in power at the time.
Can a true domain expert with deep knowledge of specific software utilize local and/or frontier models to build a competing system in a fraction of the time and cost required years ago? Yes. Absolutely—and every day, it is becoming more feasible.
About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.
For details, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.
As a technology consultant specializing in automation and integration of all things Advent, I have helped hundreds of firms make the financial reports and statements they envision a reality. In the past, those projects may have been slowed to some degree by the more obvious technical challenges: creating the mockups, subsequent report development, and testing/validation, but those aren’t the only things that make revamping statements time-consuming.
This statement mockup was created in about five minutes using Claude. No data provided here is real.
It is also what occurs within an organization as a precursor to any possible statement redesign and in tandem with an ongoing statement redesign that takes time. Changing statements requires that principals buy into the idea and believe that changing the statements, which very likely have been in use for many years, is a priority. Statement redesign doesn’t happen in a vacuum. Along the way, a lot can happen. These types of projects can be put on hold, as firms planning to update their reports may also be considering changing to another platform that might offer better reporting as a feature.
There are several factors that go into choosing a new platform, and I wouldn’t make a generalized recommendation related to that. However, if moving to a new platform is primarily about improved reporting, it is prudent to see what you can do with your existing platform before you change it.
Historical Mockups
Over the years, I have been provided with an assortment of exhibits cut out from other firms’ reports, sketched approximations of what the reports should look like, and entire report packages from other firms with a request to reproduce them. In the past, mocking up reports was something that could take hours or days. If a client didn’t already have something very specific in mind, I would provide them with report samples to review. Working from those samples as general ideas of what we could do, clients would create mockups of the reports they wanted.
Today, creating your next-generation report packages can be quicker than ever thanks to a wide variety of AI tools that are well-suited to the task. In some cases, you can create presentation-quality mockups in minutes. AI should not be used as a substitute for creative human thought and ingenuity, but working with AI tools undoubtedly speeds the process of taking your ideas and transforming them into a presentation-quality visualization that can be shared with your peers.
When done with the proper approach, tools, and infrastructure in place, you can go from having mockups to having live reports you can use in a fraction of the time it would have taken years ago, and you don’t need to change your PMS platform from Axys or APX to get these types of reports.
Data and Reporting Processes
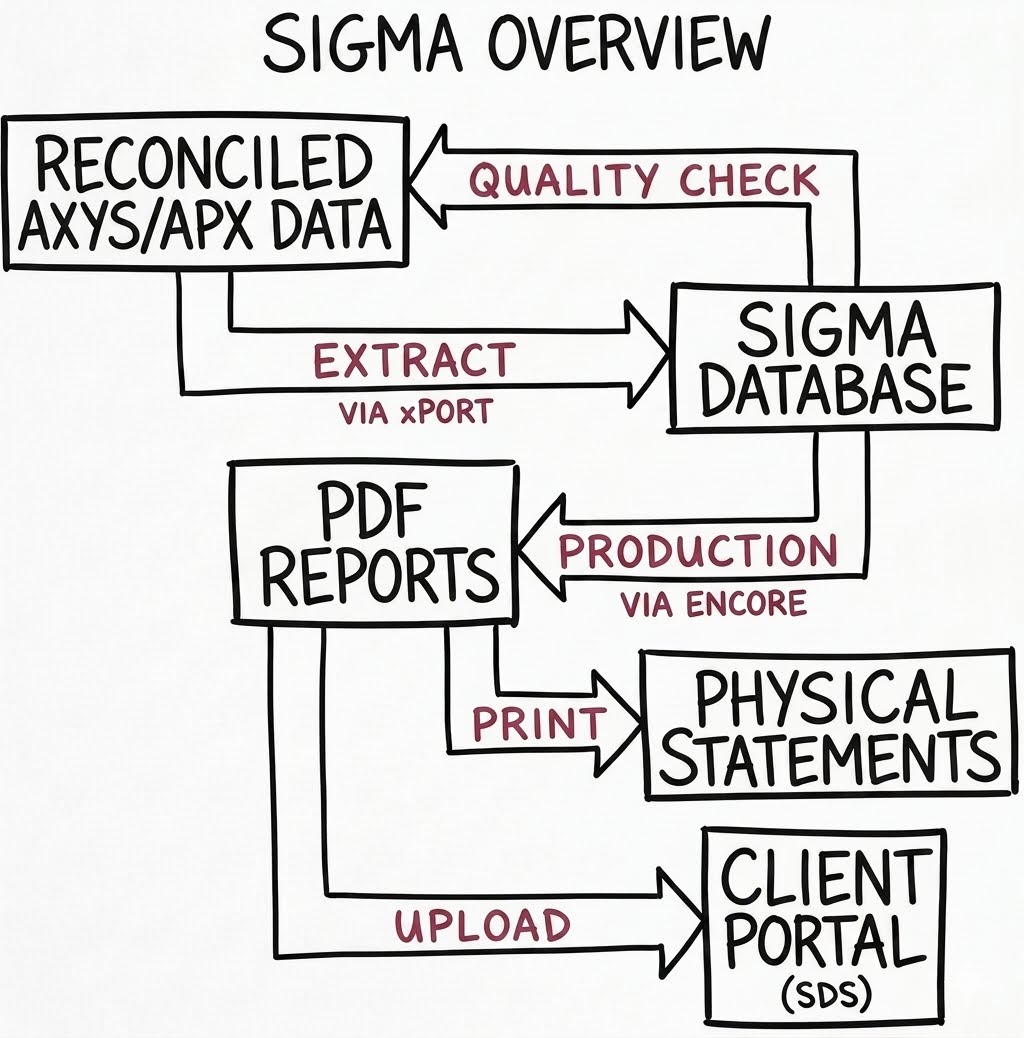
The key is having the underlying data from Axys or APX in a modern data warehouse and access to qualified tech resources to update any additional queries and data feeds you may need for the reports you want to design. That infrastructure, along with workflows that leverage it, empowers you to own your data and reporting processes. The image below illustrates my chosen approach to providing high-end investment reporting solutions to investment professionals for many years.
Next Gen Reports
While that fundamental approach hasn’t changed, the way we create reporting solutions has transformed with improvements in the technology available to us. Traditional report-writing tools could certainly be used to develop reports that are first produced as mockups, but it is no longer necessary. Instead, we can simply prompt the AI tool of our choice to create a program to populate the reports.
So long as you have the Advent data necessary to produce the reports in an acceptable database format, you should be able to populate the new reports almost immediately. If you don’t have the necessary Advent data in a data warehouse yet, that process has also never been easier than it is today. Advent subject matter experts like myself should expedite that process significantly and ensure that the data extracted is correct, but once again, AI tools are making ETL and data warehouse projects much easier than they have been in the past.
That said, pulling the data en masse is a larger, more complex project that, for now, may still be best left to those with specific expertise doing it. A data warehouse isn’t just a bunch of tables. The structure of the tables, queries, and relationships between them facilitates your ability to create additional queries and reports more efficiently.
Reports like the Portfolio Statement included in this blog are just a sample of what is possible. If you can imagine it and create a detailed system prompt describing what you want, AI tools like Claude can help you make it a reality.
There really is no time like the present to update your client statements.
About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.
For details, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.
Gamers are having a rough go of it this year and understandably feeling betrayed by one of their long-time hardware darlings, Nvidia. As you may have heard, Nvidia and other companies like Micron are prioritizing the needs of big business’ AI requirements over gamers and consumers that don’t wield as much sway over their bottom line. This blog post isn’t going to make gamers-at-large any happier, but in my defense, this really isn’t anything new. For as long as I can remember, I have considered buying a decent GPU for a new desktop PC a prudent and reasonable business expense.
Early on, the GPUs I purchased were intended to ensure support for multiple monitors, but as the technology required to support multiple monitors became ubiquitous, I continued to buy GPUs for special circumstances where I knew users like me could benefit from enhanced GPU processing. If you value your time and that of your fellow employees and clients, you need to champion investments that empower and facilitate your team’s ability to not only meet ongoing technology challenges but also provide them with the tools that will enable them to exceed expectations in the future.
There is perhaps no better example of this than the implementation of AI at your office, and I am not talking about using an AIPC with Copilot. I mean real-world implementation: running multiple local LLMs simultaneously, LLM orchestration and coding agents (e.g., Claude Code), building and using AI agents (e.g., OpenClaw), using, creating and hosting MCP servers, implementing REST API integration, et cetera. While AI cloud resources, such as frontier foundation models operating within AI factories, can be dramatically more powerful and appear less expensive than purchasing local hardware, the larger issue of data privacy is the elephant in the room. For me, this issue is twofold: I cannot put my intellectual property or any part of my clients’ private data at the mercy of what may turn out to be false security promises as AI use agreements with providers continue to evolve.
The overriding concern of data security puts users in a situation where they are limited in what they can do while using cloud resources. Users may not feel comfortable attempting certain things on cloud resources due to concerns over security, and rightly so. The answer to these concerns is clear AI use policies and systems – that dictate acceptable use of cloud and local AI resources. Those same policies and systems should simultaneously facilitate the ability to use AI in productive ways and enforce data security without handicapping technological progress. AI is not the be-all and end-all of productivity, but it can be a valuable tool when used responsibly.
Apple Intelligence’s handiwork via Playground clearly illustrating why we need to check AI work.
Game-Changing Technology
It is easy to ignore minor changes in processing power year to year, but when true paradigm-shifting tech becomes available and affordable, we need to act on it. This is the thing that makes me buy new hardware. The Nvidia GeForce RTX 5090 (“5090”) and hardware of its ilk are game-changing. Their affordability may be debatable, but if you aren’t able to use them, or superior tech options, you are operating at a technological and competitive disadvantage to your peers. With these issues in mind, I strongly recommend systems on par with the Alienware Area-51 Gaming Desktop (model AAT2265) or better for complex local AI use cases.
Six Reasons to Consider Buying the Dell Alienware Area-51 Gaming Desktop for Local AI Use Cases
CPU – The AMD Ryzen 9 9950X3D CPU has excellent single-thread processing speed, superior multithreaded processing speed, and a large cache. It offers power without compromise. One of my aims when purchasing a new desktop is to never have to upgrade the equipment during the life of the purchase, and that should be possible with this system. There is an option to get an Intel Core Ultra 9 285K, but I am not a huge fan of using the Arrow Lake architecture for AI. Additionally, being able to select a PCIe 5 NVMe for primary/OS storage means that you can remove the most obvious remaining local processing speed bottleneck.
Market forces – The expectation of constrained future supply due to AI data center demands taking precedence over SMBs and consumers makes buying now more appealing than waiting until later, when scarcity and corresponding increased demand could impact buying power.
5090 availability – This local LLM beast facilitates private use of decent-size LLMs (30B parameter models run very fast; 70B parameter models are useable.). AI is a tool we use to get our jobs done as efficiently as possible. This is simply a cost of doing business. There are other options, but this is currently the fastest GPU you can buy short of enterprise-level hardware, where the cost increases significantly. Due to 5090 availability issues, buying the GPU bundled in a PC gaming build may be the easiest way to get one.
Competitive pricing – Dell’s Alienware pricing is reasonable given the current premiums on 5090 GPUs. You could get similarly configured gaming Desktop PCs for considerably less, but the Alienware price point offers superior build quality. You could also spend a lot more money buying similarly configured “workstation” hardware, which might provide a better upgrade path, but you would likely be paying enterprise prices.
Silence and build quality – When you set it up you should notice a deafening silence in comparison to similar systems. The case is extremely well-designed to keep the system cool and quiet.
Onsite support and hardware/driver continuity – You can be confident that Dell will show up to service the PC if needed. It weighs a ton. Nobody from your office will want to carry it anywhere for service… ever. Dell is also very good at making updated drivers available when they become necessary.
The latest Area-51 build has been out since January of 2025 in Intel CPU options, but Dell added AMD options to the configuration in November of 2025. Based on my experience, even though Dell quoted shipping at roughly a month, they shipped it quicker. The system I ordered in early January 2026 arrived in less than two weeks. It comes with a single year of onsite support, but I added three years to it, and if you buy one, you probably should too. For those curious about the benchmarks, I ran PassMark’s PerformanceTest on it and have included the results below.
Dell Alienware Area-51 Gaming Desktop (model AAT2265) Passmark PerformanceTest results. Compare your PC here.
The Evolution of Local AI Use Cases
Back in 2020, during the crypto boom, I bought a Nvidia GeForce RTX 2060 Super GPU with 8GB VRAM, which cost $500 at the time. It is not a barnburner by today’s standards, but it can run the OpenAI/gpt-oss-20b model well enough on LM Studio. I also have a notebook with an NVIDIA GeForce RTX 4060 Laptop GPU. That too has 8GB of VRAM and can run local LLMs way faster than the old desktop.
These systems enabled me to run, use, and test local LLMs to a certain point, but the results weren’t fantastic. I am short on patience when it comes to waiting for computers to do things. As I tried increasingly complex models and tasks locally, I reached some predictable limitations: context, first token, and tokens per second. Watching my computer render characters in slow motion while using larger LLMs made me wonder how much of a difference running those same models on a 5090 would make. The difference is night and day. I have zero regrets about this purchase.
One interesting takeaway from the experience of using the 5090 and running many tests between the various systems I have is that model results can change when it is run on different hardware. Ideally, they won’t, but your hardware affects how the model is executed by a local AI model runner, which can influence its output. For example, I ran the same version of LM Studio with identical models and settings to provide both my old and new desktop systems with the same prompt. Logically, you might think that you would get the same results, but in fact you get different results.
The result from my old desktop was terse and simple, while the result from my new desktop was comprehensive. Though I theoretically understand how AI works and could have anticipated some differences between the results due to the variability of calculations between hardware, I was admittedly surprised. Seeing the difference firsthand adds context to my understanding.
I wanted to attribute this positive difference to my faster hardware, but that would be incorrect. Mathematically speaking, the output is simply different because the hardware is different, and the fact that the response is comprehensive on my new desktop should be purely coincidental. On closer inspection, the model I used (OpenAI/gpt-oss-20b) likely ran the prompt under constraints when it was run on the 2060 Super with 8GB VRAM. That would have caused GPU offloading (since the model size is 12GB), noise, and numerical degradation in calculations. Those issues likely created a bias towards a less comprehensive answer.
Moving Forward
Given the opportunity cost, ongoing demands of AI data centers for PC memory, storage and GPUs, and a perceived scarcity issue that will persist for years, now seems like a better time to purchase a 5090 than later when it may not be possible. Please note this computer makes sense for me and other power users that can benefit from having a 5090 for local AI use cases, but it wouldn’t be a good choice for users that don’t fit that profile. If you are interested in learning about using local AI resources almost any Nvidia GeForce RTX 50 series GPU with at least 8GB VRAM could be a good starting point.
In the PC/GPU world, VRAM ultimately determines how large a model you can use fully on the GPU and how many models you can use simultaneously. A larger model size typically corresponds with greater training depth, capability, and sophistication, which often equates to less iterative work and greater user productivity in the end. When you run out of VRAM, your system attempts to compensate by offloading portions of the model to RAM and CPU (aka GPU offloading), which slows down processing noticeably due to lower bandwidth and higher latency. If you attempt to use more total memory than is available, the model may fail to load or the system may slow dramatically.
Using a Mac with unified memory instead of a PC with a discrete GPU removes the hard VRAM boundary and reduces the performance cliff associated with GPU offloading, but you are still limited to whatever unified memory your Mac has. Assuming you can fit the model(s) in use and their associated KV (Key-Value) cache — which scales with context length — into the 5090’s 32GB of VRAM, your typical Mac isn’t going to outperform a 5090 in raw inference speed.
If you are serious about working with AI locally, you may want to step up to a Nvidia GeForce RTX 50 series GPU with at least 16GB of VRAM, which would provide a longer runway for experimentation. Either option (8GB or 16GB) shouldn’t break the bank compared to a 5090. Buying a cheaper GPU will allow you to work with local AI resources and become familiar with the tools, but if all goes well, you may wish you purchased a 5090 GPU or something capable of running even larger models concurrently, such as a high-end Mac Studio (M3 Ultra).
About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.
To learn more, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.
Over the years I have published many blogs. Almost none of them are as frequently visited as Getting Data In and Out of Advent APX and Axys. That is a good indicator that the topic remains relevant, but a long time has passed since it was published. If you have a recent version of APX today, there is another option that was not available back then – RESTful API. Though I knew the functionality existed within more recent versions of APX, I hadn’t had the chance to implement it with a client yet.
Last year, an APX user approached me, seeking to utilize Advent Software’s API to create data pipelines between APX and their in-house MS SQL Server Data Warehouse (DW). The APX user identified this work as a prerequisite for them to fully migrate from Axys to APX. They wanted to maintain the high-level integration they had created between their DW and Axys in APX.
I was somewhat concerned because I had researched previous APX versions related to the API and knew of some of the issues early adopters had encountered. Given that information, I had some trepidation about obligating myself to a project that required implementing the API. At the time I was not convinced, via first-hand experience, that the API would work reliably for their planned application of it.
I tempered the prospective client’s expectations and proposed a flat-rate job focused on determining the feasibility of doing APX API integration in their environment. Our end goal was to develop a couple of data pipelines between the DW and APX, with the caveat that those deliverables, developed in Python and/or JavaScript, would be proof-of-concept work and not necessarily ready for production use.
Together we successfully completed the project in an APX v21.x environment self-hosted by the client. The majority of the work was done over the course of a couple of months and the deliverables were ready to be moved into production almost immediately afterwards, but there were some challenges along the way. In most of the instances detailed below, we looped Advent in for assistance, and they did a commendable job helping us resolve the issues promptly.
Error 403 – Initially, we were getting an error when attempting to use the API. We reached out to Advent, and they noted that the most recent Cumulative Hot Fixes (CHF) update wasn’t applied and recommended that we install it. Applying the CHF update resolved the error, and the API worked as expected.
Postman functionality – There were a couple of days where Postman was completely unresponsive. During that brief period, we had difficulty doing even the most basic API testing. This issue seemed to resolve itself, but we may also have logged out of Postman and logged back in.
Error 500 writing data to APX – During dev the functionality to read APX data was working very well, but we found that attempting to write data to APX generated an Internal Server Error. I assumed that this meant that the data was not being written to APX. After looping Advent in for another call, we discovered that although the error was being generated, the data was being successfully written to APX. Advent indicated that they would put a fix request in, but it might not happen because v21.x was sunset. With some reservations, I updated my code to ignore the error 500 when we wrote selective data to APX via the API.
If you do reach out to Advent for assistance, make sure you have Postman installed. Advent has no desire to review your code. They will want to test the functionality of the API with you using Postman.
Visual Studio screenshot of Python code sample illustrating API use.
What is Required to Get Started with the API?
Utilizing the API requires some detailed set up and work to get up to speed. It probably won’t be something that just works without some troubleshooting, and there is a bit of a learning curve. The following list may not cover everything you need to do to get up and running with the API, but it is a good place to start. I wish there had been a better resource for me when I started working with APX’s REST API.
Here are some tips that should help those interested in implementing the API:
Make sure you are on the latest CHF for your current version of APX. If the latest hot fixes have not been installed, you may have problems trying to utilize the API.
Download the Advent Portfolio Exchange REST APIs Postman Collection from the Advent Community website.
Create a Postman account if you don’t already have one, and locally install the Postman software.
Load the collection into your Postman profile and review the documentation completely.
Do a search on the API in the Advent community site and read through some of the threads. The code samples there were simple, but helpful.
Create the client/credential and verify its existence via SSMS. The client is persistent, so once you have created it, you shouldn’t have to create it again unless you update APX. Verify the existence of the client (e.g., cc.postman) in the APX dbo.clients table. If you have trouble creating the client using your code, try using the PowerShell script to create the client.
The user profile you are using needs to have appropriate rights. Though we escalated my individual user rights in all the documented required areas, I eventually started using the admin user profile, which worked more reliably in our environment. I believe Advent recommends using the admin user profile if possible.
Test basic APX API functionality in Postman to make sure it works before attempting to create code via C#, Python, JavaScript, et cetera that leverages the API.
Once you have completed the set up required and can use the API to read and write data to APX, you are ready to build out your solution. If you have trouble with your implementation, validate specific functionality of the API with Postman.
Calling the API
Almost any use case of the API to write or read data from the APX requires the following steps:
Get IdentityServer base address from APX authentication configuration.
Get token endpoint from IdentityServer configuration.
Get token with client_credentials grant type.
Perform whatever API action you want (multiple calls to the API with the access_token are fine).
End your API Session. The API utilizes one of your APX seats while the session is active.
Those familiar with API use and Python are likely aware that manipulating data can necessitate working with JSON as well as Python dictionaries. As an example, in order to read data from APX and write data from the DW into APX that is different from what is already in APX, you may need to:
Query APX for the relevant data via the API, which creates a JSON file.
Query the DW for the relevant data.
Load the JSON data received from APX into a Python dictionary.
Parse and compare the APX data from the Python dictionary with the records from the DW.
Add the records that meet the criteria to the JSON payload.
Send a patch request via the APX API.
The following diagram details this workflow.
To wrap up the project, I created a PowerPoint presentation summarizing and detailing what we did and how it all works to empower the internal development team to understand, troubleshoot, and replicate my work if they need to in the future. I am always available to support the solutions I create, but I prefer that my customers call me because they want to, not because they need to.
Why would you want to use the API instead of IMEX?
There are pros and cons to using the API. It presents an opportunity to use a single unified methodology to integrate data in your environment but may fall short of that depending on the specific needs of your firm.
The pros of using the API include the fact that is is a more modern approach to extracting and importing data at a granular level. The API can be used to pull data such as holdings, select time period performance, etc. In some use cases, APX users are likely extracting and transforming data that they drop into a DW. Some of those transformations, such as recalculating performance figures, may not be necessary when utilizing the API. The API has the potential to be more secure but given that the default password for admin user in APX frequently doesn’t get changed, it probably isn’t any more secure than IMEX in most self-hosted APX environments.
The cons of using the API are that some data elements may still be in flux. Reading and writing certain data points may not be possible via the API, which could force you to use IMEX or other methods (e.g., Replang, public views, stored procedures, SSRS) in addition to the API. It also may be difficult developers that aren’t Advent APX Subject Matter Experts (SMEs) to bridge this gap. Conversely, it may be difficult for those SMEs that are not developers familiar with the API use to implement it on their own.
Using well-established APX import and export methods like IMEX may still be the most efficient and reliable way to import and extract certain data elements from APX. However, going forward, the growing maturity of Advent’s REST API should force tech-savvy management, users, and integrators to ask “Should we be using the APX API to do this?” as they look to forge a modern data stack that integrates APX data, and meets AI-driven demands for more robust data access.
About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.
To learn more, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.


 About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.