Latest Entries »

Earlier this year, when software stocks were taking a beating related to the heights of AI enthusiasm, a client reached out to me for my opinion on whether AI might be used by domain experts, such as myself, to create competing products capable of supplanting established software firms like Advent and others at a fraction of the price due to a lower cost base.

An abstract representation of a cosmic explosion, with rays of light emanating from a bright central core against a dark starry background.

At the time, I acknowledged that it was possible, but more likely to happen at smaller firms. Investment professionals are stereotypically risk-averse in their business practices and the production software they utilize to run their businesses. While the largest investment firms are better suited to tolerating risk from a resource standpoint, they are also the least likely to take on what they might consider unnecessary risk. As a result, larger firms as a whole are slower to replace mainstream products with upstart offerings that have an unproven track record.

However, a more likely possibility has emerged: firms currently running vendor software—motivated by the costs and limitations of those products—may simply create their own systems using AI to aid them in the process. I have already seen signs that some firms are doing this and feel comfortable doing so. I am not necessarily recommending it, but I understand the motivation.

If you are paying substantial fees for systems you believe you could replace, why wouldn’t you? The key here is understanding what these systems actually do. A vendor with a forty-year track record has built a product that almost certainly handles details that an AI-assisted or ‘vibe-coding’ alternative (with a relatively short window of development and testing) does not; however, that may not matter much if you are only looking for 60% to 80% of the functionality of the product you are replacing.

When I compare products in the investment space, there are clear differentiators between older-class solutions and newer-class solutions. Those differentiators once would have represented a significant hurdle for a competing product to match, but AI makes it much easier.

As an example, consider the HTML attachment below, which summarizes hypothetical investments for a fictitious company and client in a format typical of newer-class solutions. I used Claude to help me produce this last month. This is something I could have done previously if a prospective client had asked me to, but I was never tempted to do so because it would have been tedious and time-consuming to perform manually. With the assistance of frontier AI models, I was able to achieve the following result, which can easily be populated from portfolio accounting data within Axys or APX. Please note that all reporting exhibits in this blog were produced using Anthropic, OpenAI, and Perplexity models and based on fictional data; disclosures on each exhibit also restate this.

The prompt was the result of a test I performed one afternoon where I asked the best-known publicly available frontier models in the cloud, as well as the best local models I can run on my Alienware Area-51 desktop, to create what I consider to be a decent report package by today’s standards. I would love to take more credit for it, but I cannot; I simply asked Claude to do it and it was done. Perplexity also did a respectable job, though it fell slightly behind Claude’s effort, while ChatGPT’s report was clean but relatively simplistic.

The local models didn’t put up much of a fight, although I may be able to improve their performance by using frontier models to design the prompts for them. It would be nice to rerun these tests using GLM-5.3 Q4 or GLM-5.3-Flash on a Mac Studio with an M5 Ultra chip and 512GB of unified memory, but I don’t have one of those yet. Naturally, if you write better prompts than I did or possess superior hardware, your results may vary.

Claude didn’t just create a pretty mockup of data in HTML like ChatGPT and Perplexity; it created JSON blocks within the HTML that I can populate programmatically from data feeds I have already created using xPort with Axys and APX. If I wanted to build an alternative system, I would be well on my way with this type of reporting right out of the gate.

Here is what I produced with Perplexity’s assistance.

Here is what I produced using ChatGPT.

The pros and cons of building versus buying remain. AI can potentially help you maintain the code, but will your staff truly understand everything they are using? Probably not. And what will it cost to maintain that code in the future? If the system is predominantly AI-coded and not fully understood by those at your firm, that cost will be determined by the “AI gods” in power at the time.

Can a true domain expert with deep knowledge of specific software utilize local and/or frontier models to build a competing system in a fraction of the time and cost required years ago? Yes. Absolutely—and every day, it is becoming more feasible.


About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.

For details, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.

As a technology consultant specializing in automation and integration of all things Advent, I have helped hundreds of firms make the financial reports and statements they envision a reality. In the past, those projects may have been slowed to some degree by the more obvious technical challenges: creating the mockups, subsequent report development, and testing/validation, but those aren’t the only things that make revamping statements time-consuming.

This statement mockup was created in about five minutes using Claude. No data provided here is real.

It is also what occurs within an organization as a precursor to any possible statement redesign and in tandem with an ongoing statement redesign that takes time. Changing statements requires that principals buy into the idea and believe that changing the statements, which very likely have been in use for many years, is a priority. Statement redesign doesn’t happen in a vacuum. Along the way, a lot can happen. These types of projects can be put on hold, as firms planning to update their reports may also be considering changing to another platform that might offer better reporting as a feature.

There are several factors that go into choosing a new platform, and I wouldn’t make a generalized recommendation related to that. However, if moving to a new platform is primarily about improved reporting, it is prudent to see what you can do with your existing platform before you change it.

Historical Mockups

Over the years, I have been provided with an assortment of exhibits cut out from other firms’ reports, sketched approximations of what the reports should look like, and entire report packages from other firms with a request to reproduce them. In the past, mocking up reports was something that could take hours or days. If a client didn’t already have something very specific in mind, I would provide them with report samples to review. Working from those samples as general ideas of what we could do, clients would create mockups of the reports they wanted.

Today, creating your next-generation report packages can be quicker than ever thanks to a wide variety of AI tools that are well-suited to the task. In some cases, you can create presentation-quality mockups in minutes. AI should not be used as a substitute for creative human thought and ingenuity, but working with AI tools undoubtedly speeds the process of taking your ideas and transforming them into a presentation-quality visualization that can be shared with your peers.

When done with the proper approach, tools, and infrastructure in place, you can go from having mockups to having live reports you can use in a fraction of the time it would have taken years ago, and you don’t need to change your PMS platform from Axys or APX to get these types of reports.

Data and Reporting Processes

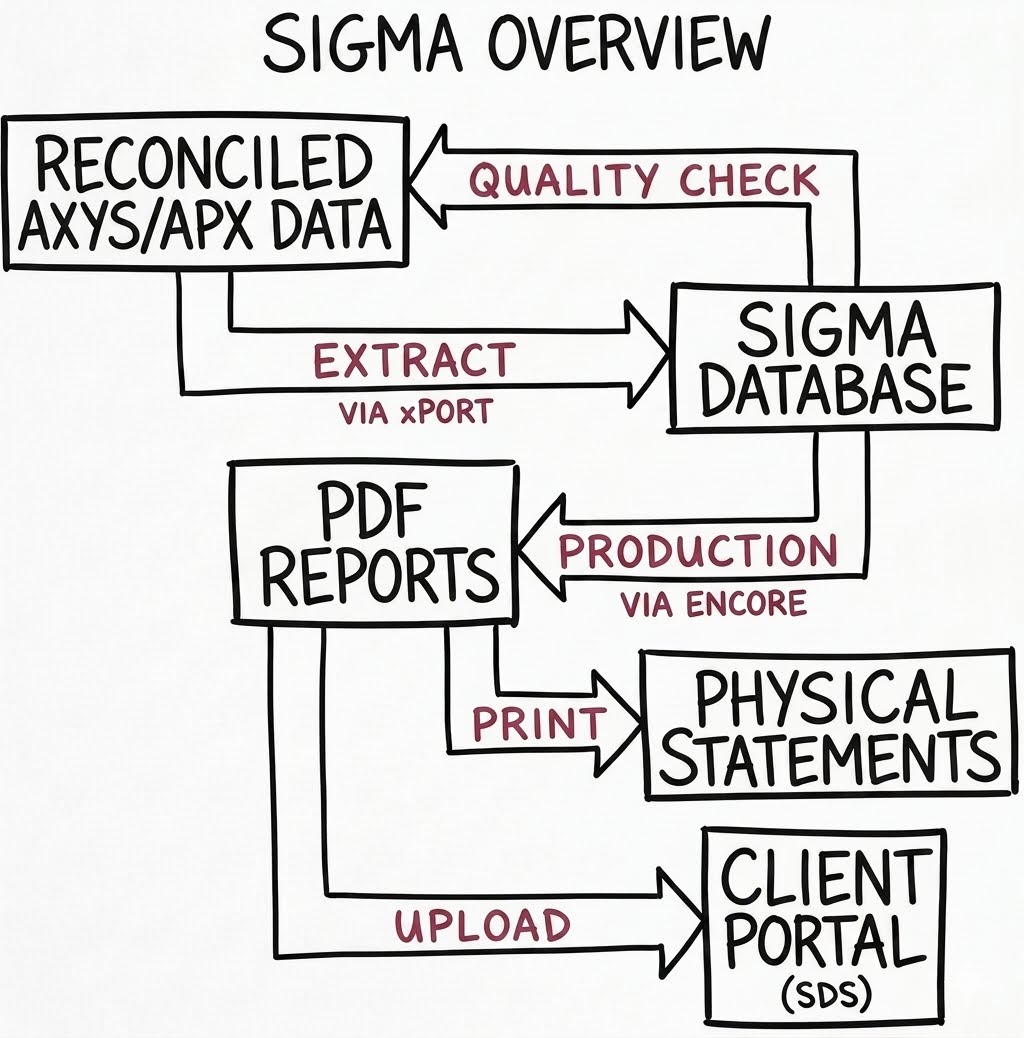
The key is having the underlying data from Axys or APX in a modern data warehouse and access to qualified tech resources to update any additional queries and data feeds you may need for the reports you want to design. That infrastructure, along with workflows that leverage it, empowers you to own your data and reporting processes. The image below illustrates my chosen approach to providing high-end investment reporting solutions to investment professionals for many years.

Next Gen Reports

While that fundamental approach hasn’t changed, the way we create reporting solutions has transformed with improvements in the technology available to us. Traditional report-writing tools could certainly be used to develop reports that are first produced as mockups, but it is no longer necessary. Instead, we can simply prompt the AI tool of our choice to create a program to populate the reports.

So long as you have the Advent data necessary to produce the reports in an acceptable database format, you should be able to populate the new reports almost immediately. If you don’t have the necessary Advent data in a data warehouse yet, that process has also never been easier than it is today. Advent subject matter experts like myself should expedite that process significantly and ensure that the data extracted is correct, but once again, AI tools are making ETL and data warehouse projects much easier than they have been in the past.

That said, pulling the data en masse is a larger, more complex project that, for now, may still be best left to those with specific expertise doing it. A data warehouse isn’t just a bunch of tables. The structure of the tables, queries, and relationships between them facilitates your ability to create additional queries and reports more efficiently.

Reports like the Portfolio Statement included in this blog are just a sample of what is possible. If you can imagine it and create a detailed system prompt describing what you want, AI tools like Claude can help you make it a reality.

There really is no time like the present to update your client statements.


About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of agile technology solutions to investors and the financial services community at large.

For details, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202 or e-mail at kshea@quartare.com.

I have been creating useful content for Advent users and the financial services firms they work with for many years now.  Part of creating the blog is therapeutic for me, part of it is a well-intentioned effort to foster goodwill by sharing the lessons I have learned with other users to reduce pain points, and some part of it is an effort to get the word out about what I do in case users find that they need someone with my unique skillset.

A watercolor painting of a pensive sculpture with a hand on its chin, surrounded by a colorful abstract background.

When ChatGPT and similar services arrived on the scene, I was somewhat concerned about what would happen if those engines sucked up the knowledgebase I have created and presented it to my audience as their own information.  There are documented ways to discourage AI bots like robots.txt, Cloudflare AI Crawl, WAF blocking and CMS-specific settings.  I know this, but early on I made a choice to allow it, rather than fight it.

Initially, I remained most worried that my knowledge would be presented without credit to where it came from, but this past week I realized that there is another issue altogether.  In the process of troubleshooting an Advent Software use case, I queried Perplexity.  I was rewarded with a page of summary information that cited Advent, AdventGuru and 13 other sources.  Some of those sources were relevant, most were not.

As I drilled down on the problem, most of the sources cited were in fact me.  So here I was querying Perplexity for assistance, and it was attempting to assist me in troubleshooting the issue using information I provided.  Some part of this makes sense and could be helpful if I were losing my faculties or wanted to query my own digital footprint related to the issue.  Neither of these apply.

I wound up resolving the issue with the user and their IT consultant in less than an hour with no part of the credit for doing it attributable to using Perplexity with its “best” model. Our solution was collaborative.  The client arranged a Teams meeting with me, and their IT consultant.  The three of us worked together to try a few things.  Eventually, we found a solution as a result of us all working together – not an AI query.  We solved it because we found the time to have a meeting and made that a priority.

In the process of writing this, I ran the same query on Opus 4.6 and GPT-5.4.  The results were very similar. My blog and other online sources of current and historical information are the data that empowers these engines to respond to practical and esoteric questions with anything relevant beyond their training data.  However, as I read though their responses to the query, it became clear that I was heavily cited without any solution being provided to the problem.

While I am flattered that my subject matter expertise is held in such high esteem by AI inference engines, I am concerned that when AI models attempting to utilize what I have written – citing me repeatedly throughout their response as a source of information – fail to provide a solution that reflects poorly on me.  In the particular case we resolved, I am almost 100% certain that a solution does not currently exist online.  I have already written a separate blog post detailing the problem and its solution, but now the question for me is, do I put that solution up on my blog? 

By doing so, I continue to provide access to users that have relied on me as a source of information that may not otherwise be discovered, documented or publicly available, but I am also empowering AI inference to parody my expertise in more meaningful ways that may make users think their favorite AI chatbot is a substitute for getting knowledge directly from the source. The latter is problematic because written works contain meaning and nuance that are lost when information is taken selectively and presented out of context.

Chatbots cannot be trusted to provide the best possible answer – only the best possible answer based on their training, parameters, capabilities, available data, and the prompts we use to query them.  My blog posts are representative breadcrumbs of my experience that I have chosen to share.  In this case, the chatbots reviewed my blogs to determine if and how something can be done, asserted that it could not be done, and then provided instructions on possible workarounds, but there was a solution that could be found without the assistance of a chatbot all along and it makes a lot more sense than the workarounds that were recommended by Perplexity and its cohorts.


Kevin Shea Impact 2010

About the Author: Kevin Shea is the Founder and Principal Consultant of Quartare; Quartare provides a wide variety of technology solutions to investment advisors nationwide.

For details, please visit Quartare.com, contact Kevin Shea via phone at 617-720-3400 x202